Snowflake to BigQuery Translator
dbt Snowflake to BigQuery Translator
Translates Snowflake dbt SQL models to Standardized BigQuery SQL. Handles SQL compilation, Jinja macro placeholder masking, BigQuery Translation Service migration workflows, AST-based config transformations, explicit type casting, JSON…
---
name: dbt-sf-to-bq-translator
metadata:
  version: "1.0.1"
  category: BigDataAndAnalytics
description: >-
  Translates Snowflake dbt SQL models to Standardized BigQuery SQL. Handles SQL
  compilation, Jinja macro placeholder masking, BigQuery Translation Service migration
  workflows, AST-based config transformations, explicit type casting, JSON extraction
  standardization, and deduplication. Use when migrating Snowflake dbt pipelines
  or models to Google Cloud BigQuery. Don't use for generic BigQuery queries or
  non-Snowflake SQL migrations.
---

# dbt Snowflake to BigQuery Translator

You are responsible for:
1.  **Dialect Translation**: Translating Snowflake dbt SQL models to Standardized Google BigQuery SQL.
Overview
You are responsible for: 1. Dialect Translation: Translating Snowflake dbt SQL models to Standardized Google BigQuery SQL. 2. Standardization & Compliance: Enforcing Google-specific standards including copyright headers at the very top of each file, explicit type casting, standardized JSON extraction, and deduplication via QUALIFY with _extracted_at. 3. Workflow Integration: Preserving dbt Jinja constructs and storing the final BigQuery-compatible models.
Manual install (npx, ZIP)
npx skills add google/skills --skill dbt-sf-to-bq-translator -g -a claude-codenpx degit google/skills/skills/cloud/dbt-sf-to-bq-translator#main ~/.claude/skills/dbt-sf-to-bq-translatorConnects with Agent Alley MCP · agentalley.io/mcp
Files included
SKILL.md10.4 KB
Read SKILL.md here
Show the full text148 lines
dbt Snowflake to BigQuery Translator
You are responsible for:
- Dialect Translation: Translating Snowflake dbt SQL models to Standardized Google BigQuery SQL.
- Standardization & Compliance: Enforcing Google-specific standards including copyright headers at the very top of each file, explicit type casting, standardized JSON extraction, and deduplication via
QUALIFYwith_extracted_at. - Workflow Integration: Preserving dbt Jinja constructs and storing the final BigQuery-compatible models.
Follow the instructions given you under migration_plan/[mig_prefix]/tasks.md. You will add your progress during operation and summary at the end to the tasks file so that human supervisor can track where you are. You recover from errors by checking the tasks file.
Prerequisites & Environment Setup
Before starting the translation, ensure your Google Cloud environment is properly configured:
- Google Cloud SDK: Install the Google Cloud SDK if not already installed.
- Authentication: Authenticate your CLI session:
gcloud auth login gcloud auth application-default login - Project Configuration: Set your active GCP project:
gcloud config set project {project_id} - Billing Account: Verify that an active Google Cloud Billing account is attached to the target project.
- Enable Required APIs: Ensure BigQuery, Migration, and Storage services are enabled:
gcloud services enable bigquerymigration.googleapis.com storage.googleapis.com bigquery.googleapis.com - Region Selection: Configure your preferred compute/BigQuery region (default recommended:
us-central1orus). See Google Cloud Locations:gcloud config set compute/region us-central1
Steps
Initialization & Setup: If you do not have a defined
mig_prefixor if the user wants to start a new translation project, you MUST first ask the user for:- Migration Project Name (e.g.
my_migration_project). - Input directory containing Snowflake SQL files.
- Output directory where BigQuery SQL files should be saved.
- GCS Bucket name for staging translation assets.
- GCP Region (e.g.
usoreu). - (Optional) Local path to a directory or
.zipfile containing source database metadata (such ascolumns.csvortables.csv). Once provided, create the tasks checklist file undermigration_plan/[mig_prefix]/tasks.mdwith unchecked tasks representing the migration steps.
- Migration Project Name (e.g.
Automated Execution via Bundled Scripts: Execute the deterministic end-to-end migration using the bundled translation script
scripts/bulk_translate_via_gcloud.py:python3 scripts/bulk_translate_via_gcloud.py \ --input <input_dir> \ --output <output_dir> \ --bucket <gcs_bucket> \ --location <region> \ [--metadata <metadata_path>]The migration tools bundled in
scripts/perform the following coordinated actions:scripts/bulk_translate_via_gcloud.py: Orchestrates end-to-end bulk migration, automating pre-processing, GCS upload, BigQuery Translation Service invocation, download, post-processing, and YAML configuration copying.scripts/dbt_translator.py: Core translation library containing the deterministic AST parser forconfig(...), Jinja placeholder masking and restoration, JSON extraction sanitization, macro auditing, casing/join standardization, and copyright header enforcement.
Detailed Translation Lifecycle (Executed by Scripts):
- Compile to Standard SQL using Placeholders (Pre-Translation):
- Read the original source dbt
.sqlfiles. Extract and strip the{{ config(...) }}header block from the top of each file. - Replace dbt macro calls with standard-SQL-compliant placeholder identifiers to prevent BigQuery Translation Service from throwing syntax errors:
- Replace
{{ source('src_name', 'table_name') }}with_DBT_SOURCE_src_name_DBTSEP_table_name_ - Replace
{{ ref('model_name') }}with_DBT_REF_model_name_
- Replace
- Eliminate Jinja curly braces (
{{ ... }}) from the SQL prior to translation, ensuring the transpiler processes 100% valid Snowflake dialect SQL.
- Read the original source dbt
- Isolate the SQL Files:
- Save these pre-processed, Jinja-free files to a staging input directory ready for GCS upload.
- Pre-Process Metadata & Translate SQL via BigQuery Translation Service:
- If a metadata path is provided, map table entries matching discovered dbt models/sources to their placeholder names in
columns.csvandtables.csv, clear catalog names to prevent namespace resolution errors, package intometadata.zip, and upload to GCS. - Upload staging SQL files to GCS:
gcloud storage cp <staging_input_dir>/*.sql gs://[YOUR_BUCKET]/migration_input/ - Create
migration_config.yamlspecifyingsnowflakeDialectas source andbigqueryDialectas target (withschemaPathpointing tometadata.zipif provided). - Trigger translation workflow:
gcloud bq migration-workflows create --location=<region> --config-file=migration_config.yaml --no-async - Download translated GoogleSQL files from GCS:
gcloud storage cp gs://[YOUR_BUCKET]/migration_output/*.sql <translated_output_dir>/
- If a metadata path is provided, map table entries matching discovered dbt models/sources to their placeholder names in
- Restore Placeholders & Re-Embed dbt Logic:
- Take the translated BigQuery SQL files and perform advanced post-processing:
- AST-Based Config Transformation: Parse the original
{{ config(...) }}block, stripping Snowflake-specific parameters likecopy_grants,transient, andsecure. Sanitize hooks (pre_hookandpost_hook) to remove invalid Snowflake commands likeALTER ICEBERG TABLE ... REFRESHorUNSET SECURE, while preserving valid ones. - Reference Resolver (Namespace Resolution): Scan the SQL for hardcoded Snowflake database/schema table paths in FROM and JOIN clauses, and map them back to native dbt
{{ ref(...) }}or{{ source(...) }}macros by resolving against discovered project models and sources. - Macro & Syntax Audit: Scan all
{{ ... }}Jinja expressions and log warnings for any custom/non-allowlisted database-specific macros. Also audit these blocks for Snowflake-specific syntax (e.g.::date,dateadd,to_date) that may have been skipped or masked, listing warning comments directly in the file. - Balanced SQL Edge-Cases Sanitization: Convert date cast suffixes (
::date->CAST(... AS DATE)), datetime cast suffixes (::timestamp->CAST(... AS TIMESTAMP)), nesteddateadd(...)calls, and intervals (- interval '5 month') inside and outside control blocks using balanced-parentheses parsers. - Copyright Header Placement: Prepend the mandatory Google copyright header at the very top of the file above the config block.
- AST-Based Config Transformation: Parse the original
- Take the translated BigQuery SQL files and perform advanced post-processing:
- Write to the New BigQuery dbt File & Copy YAML Configurations:
- Save the newly assembled, BigQuery-compatible files preserving directory structure. Also, copy all
.yml/.yamlfiles from the input directory to the output directory.
- Save the newly assembled, BigQuery-compatible files preserving directory structure. Also, copy all
- Compile to Standard SQL using Placeholders (Pre-Translation):
Put a summary to the tasks file at the end.
Before handing over, ask for user approval for the outcome. Apply necessary changes from the user.
Mark your task is done in the tasks file.
Mandates & Behavioral Rules
1. Mandatory File Header
Every translated file MUST start with the following exact header at the very top:
# Copyright 2026 Google. This software is provided as-is, without warranty or
# representation for any use or purpose. Your use of it is subject to your
# agreement with Google.
2. Standardized JSON Extraction
Never use Snowflake colon notation or BigQuery JSON_VALUE. Always use the following pattern:
- Rule:
CAST(JSON_EXTRACT_SCALAR(json_column, '$.path') AS TYPE) - Mandatory Casting:
- IDs (primary/foreign):
AS INT64for all system IDs (do not useNUMERICfor IDs). - Boolean Flags:
AS BOOL - Strings:
AS STRING(do not wrap inNULLIFunless explicitly required to handle empty/null strings in source). - Timestamps:
AS TIMESTAMP
- IDs (primary/foreign):
3. Explicit Type Safety
- Comparisons: Always use
CASTon both sides of a join or filter if types are not identical. UseAS STRINGfor universal comparison safety if necessary. - ID Fields: Prefer
INT64for all system IDs (e.g.,ticket_id,user_id). - Null Handling:
- For placeholder columns, always use explicit type casting:
CAST(NULL AS TYPE).
- For placeholder columns, always use explicit type casting:
4. Prescriptive String & Date Functions
- Truncation: Use
LEFT(col, length)orSUBSTR(col, 1, length). - Search: Use
LOWER(col) LIKE '%pattern%'instead ofREGEXP_CONTAINS. - Date Add: Use
DATE_ADD(CAST(col AS DATETIME), INTERVAL num HOUR).
5. Mandatory Deduplication & Joins
- Deduplication: If the source model requires deduplication on a primary key:
- Rule: Use a
row_number() over (partition by [PRIMARY_KEY] order by [TIMESTAMP] desc) as rncolumn in the base CTE, and applyqualify rn = 1directly on that CTE.
- Rule: Use a
- Joins: Use
LEFT JOINwhen joining to custom field or attribute tables (e.g.,exploded_arraypatterns) to prevent dropping records.
6. Preserve Jinja Constructs
Do not alter {{ config(...) }}, {{ ref(...) }}, or {{ source(...) }}. Keep {% if is_incremental() %} blocks functional. Do not inject historical data unions or other custom macros/tables unless they are present in the source files.
Outputs
You will output BigQuery-compatible dbt SQL models under migration_plan/[mig_prefix]/translated_models/. The translated files must strictly adhere to the structural pattern and dialectic formatting.
For translation examples, see: dbt_migration_patterns.md
Constraints
Before handing over to the root agent, first get approval from the user about the translated models. After applying user's requests, then hand over the root agent.
| 1 | |
| 2 | name dbt-sf-to-bq-translator |
| 3 | metadata |
| 4 | version "1.0.1" |
| 5 | category BigDataAndAnalytics |
| 6 | description >- |
| 7 | Translates Snowflake dbt SQL models to Standardized BigQuery SQL. Handles SQL |
| 8 | compilation, Jinja macro placeholder masking, BigQuery Translation Service migration |
| 9 | workflows, AST-based config transformations, explicit type casting, JSON extraction |
| 10 | standardization, and deduplication. Use when migrating Snowflake dbt pipelines |
| 11 | or models to Google Cloud BigQuery. Don't use for generic BigQuery queries or |
| 12 | non-Snowflake SQL migrations. |
| 13 | |
| 14 | |
| 15 | # dbt Snowflake to BigQuery Translator |
| 16 | |
| 17 | You are responsible for: |
| 18 | **Dialect Translation**: Translating Snowflake dbt SQL models to Standardized Google BigQuery SQL. |
| 19 | **Standardization & Compliance**: Enforcing Google-specific standards including copyright headers at the very top of each file, explicit type casting, standardized JSON extraction, and deduplication via `QUALIFY` with `_extracted_at`. |
| 20 | **Workflow Integration**: Preserving dbt Jinja constructs and storing the final BigQuery-compatible models. |
| 21 | |
| 22 | Follow the instructions given you under `migration_plan/[mig_prefix]/tasks.md`. You will add your progress during operation and summary at the end to the tasks file so that human supervisor can track where you are. You recover from errors by checking the tasks file. |
| 23 | |
| 24 | # Prerequisites & Environment Setup |
| 25 | |
| 26 | Before starting the translation, ensure your Google Cloud environment is properly configured: |
| 27 | **Google Cloud SDK**: Install the [Google Cloud SDK] if not already installed. |
| 28 | **Authentication**: Authenticate your CLI session: |
| 29 | |
| 30 | gcloud auth login |
| 31 | gcloud auth application-default login |
| 32 | |
| 33 | **Project Configuration**: Set your active GCP project: |
| 34 | |
| 35 | gcloud config set project {project_id} |
| 36 | |
| 37 | **Billing Account**: Verify that an active Google Cloud Billing account is attached to the target project. |
| 38 | **Enable Required APIs**: Ensure BigQuery, Migration, and Storage services are enabled: |
| 39 | |
| 40 | gcloud services enable bigquerymigration.googleapis.com storage.googleapis.com bigquery.googleapis.com |
| 41 | |
| 42 | **Region Selection**: Configure your preferred compute/BigQuery region (default recommended: `us-central1` or `us`). See [Google Cloud Locations]: |
| 43 | |
| 44 | gcloud config set compute/region us-central1 |
| 45 | |
| 46 | |
| 47 | # Steps |
| 48 | |
| 49 | **Initialization & Setup**: If you do not have a defined `mig_prefix` or if the user wants to start a new translation project, you **MUST** first ask the user for: |
| 50 | Migration Project Name (e.g. `my_migration_project`). |
| 51 | Input directory containing Snowflake SQL files. |
| 52 | Output directory where BigQuery SQL files should be saved. |
| 53 | GCS Bucket name for staging translation assets. |
| 54 | GCP Region (e.g. `us` or `eu`). |
| 55 | (Optional) Local path to a directory or `.zip` file containing source database metadata (such as `columns.csv` or `tables.csv`). |
| 56 | Once provided, create the tasks checklist file under `migration_plan/[mig_prefix]/tasks.md` with unchecked tasks representing the migration steps. |
| 57 | |
| 58 | **Automated Execution via Bundled Scripts**: |
| 59 | Execute the deterministic end-to-end migration using the bundled translation script `scripts/bulk_translate_via_gcloud.py`: |
| 60 | |
| 61 | python3 scripts/bulk_translate_via_gcloud.py \ |
| 62 | --input <input_dir> \ |
| 63 | --output <output_dir> \ |
| 64 | --bucket <gcs_bucket> \ |
| 65 | --location <region> \ |
| 66 | [--metadata <metadata_path>] |
| 67 | |
| 68 | The migration tools bundled in `scripts/` perform the following coordinated actions: |
| 69 | `scripts/bulk_translate_via_gcloud.py`: Orchestrates end-to-end bulk migration, automating pre-processing, GCS upload, BigQuery Translation Service invocation, download, post-processing, and YAML configuration copying. |
| 70 | `scripts/dbt_translator.py`: Core translation library containing the deterministic AST parser for `config(...)`, Jinja placeholder masking and restoration, JSON extraction sanitization, macro auditing, casing/join standardization, and copyright header enforcement. |
| 71 | |
| 72 | **Detailed Translation Lifecycle (Executed by Scripts)**: |
| 73 | **Compile to Standard SQL using Placeholders (Pre-Translation)**: |
| 74 | Read the original source dbt `.sql` files. Extract and strip the `{{ config(...) }}` header block from the top of each file. |
| 75 | Replace dbt macro calls with standard-SQL-compliant placeholder identifiers to prevent BigQuery Translation Service from throwing syntax errors: |
| 76 | Replace `{{ source('src_name', 'table_name') }}` with `_DBT_SOURCE_src_name_DBTSEP_table_name_` |
| 77 | Replace `{{ ref('model_name') }}` with `_DBT_REF_model_name_` |
| 78 | Eliminate Jinja curly braces (`{{ ... }}`) from the SQL prior to translation, ensuring the transpiler processes 100% valid Snowflake dialect SQL. |
| 79 | **Isolate the SQL Files**: |
| 80 | Save these pre-processed, Jinja-free files to a staging input directory ready for GCS upload. |
| 81 | **Pre-Process Metadata & Translate SQL via BigQuery Translation Service**: |
| 82 | If a metadata path is provided, map table entries matching discovered dbt models/sources to their placeholder names in `columns.csv` and `tables.csv`, clear catalog names to prevent namespace resolution errors, package into `metadata.zip`, and upload to GCS. |
| 83 | Upload staging SQL files to GCS: |
| 84 | `gcloud storage cp <staging_input_dir>/*.sql gs://[YOUR_BUCKET]/migration_input/` |
| 85 | Create `migration_config.yaml` specifying `snowflakeDialect` as source and `bigqueryDialect` as target (with `schemaPath` pointing to `metadata.zip` if provided). |
| 86 | Trigger translation workflow: |
| 87 | `gcloud bq migration-workflows create --location=<region> --config-file=migration_config.yaml --no-async` |
| 88 | Download translated GoogleSQL files from GCS: |
| 89 | `gcloud storage cp gs://[YOUR_BUCKET]/migration_output/*.sql <translated_output_dir>/` |
| 90 | **Restore Placeholders & Re-Embed dbt Logic**: |
| 91 | Take the translated BigQuery SQL files and perform advanced post-processing: |
| 92 | **AST-Based Config Transformation**: Parse the original `{{ config(...) }}` block, stripping Snowflake-specific parameters like `copy_grants`, `transient`, and `secure`. Sanitize hooks (`pre_hook` and `post_hook`) to remove invalid Snowflake commands like `ALTER ICEBERG TABLE ... REFRESH` or `UNSET SECURE`, while preserving valid ones. |
| 93 | **Reference Resolver (Namespace Resolution)**: Scan the SQL for hardcoded Snowflake database/schema table paths in FROM and JOIN clauses, and map them back to native dbt `{{ ref(...) }}` or `{{ source(...) }}` macros by resolving against discovered project models and sources. |
| 94 | **Macro & Syntax Audit**: Scan all `{{ ... }}` Jinja expressions and log warnings for any custom/non-allowlisted database-specific macros. Also audit these blocks for Snowflake-specific syntax (e.g. `::date`, `dateadd`, `to_date`) that may have been skipped or masked, listing warning comments directly in the file. |
| 95 | **Balanced SQL Edge-Cases Sanitization**: Convert date cast suffixes (`::date` -> `CAST(... AS DATE)`), datetime cast suffixes (`::timestamp` -> `CAST(... AS TIMESTAMP)`), nested `dateadd(...)` calls, and intervals (`- interval '5 month'`) inside and outside control blocks using balanced-parentheses parsers. |
| 96 | **Copyright Header Placement**: Prepend the mandatory Google copyright header at the very top of the file above the config block. |
| 97 | **Write to the New BigQuery dbt File & Copy YAML Configurations**: |
| 98 | Save the newly assembled, BigQuery-compatible files preserving directory structure. Also, copy all `.yml`/`.yaml` files from the input directory to the output directory. |
| 99 | |
| 100 | Put a summary to the tasks file at the end. |
| 101 | Before handing over, ask for user approval for the outcome. Apply necessary changes from the user. |
| 102 | Mark your task is done in the tasks file. |
| 103 | |
| 104 | # Mandates & Behavioral Rules |
| 105 | |
| 106 | ### 1. Mandatory File Header |
| 107 | Every translated file **MUST** start with the following exact header at the very top: |
| 108 | |
| 109 | # Copyright 2026 Google. This software is provided as-is, without warranty or |
| 110 | # representation for any use or purpose. Your use of it is subject to your |
| 111 | # agreement with Google. |
| 112 | |
| 113 | |
| 114 | ### 2. Standardized JSON Extraction |
| 115 | Never use Snowflake colon notation or BigQuery `JSON_VALUE`. Always use the following pattern: |
| 116 | **Rule**: `CAST(JSON_EXTRACT_SCALAR(json_column, '$.path') AS TYPE)` |
| 117 | **Mandatory Casting**: |
| 118 | IDs (primary/foreign): `AS INT64` for all system IDs (do not use `NUMERIC` for IDs). |
| 119 | Boolean Flags: `AS BOOL` |
| 120 | Strings: `AS STRING` (do not wrap in `NULLIF` unless explicitly required to handle empty/null strings in source). |
| 121 | Timestamps: `AS TIMESTAMP` |
| 122 | |
| 123 | ### 3. Explicit Type Safety |
| 124 | **Comparisons**: Always use `CAST` on both sides of a join or filter if types are not identical. Use `AS STRING` for universal comparison safety if necessary. |
| 125 | **ID Fields**: Prefer `INT64` for all system IDs (e.g., `ticket_id`, `user_id`). |
| 126 | **Null Handling**: |
| 127 | For placeholder columns, always use explicit type casting: `CAST(NULL AS TYPE)`. |
| 128 | |
| 129 | ### 4. Prescriptive String & Date Functions |
| 130 | **Truncation**: Use `LEFT(col, length)` or `SUBSTR(col, 1, length)`. |
| 131 | **Search**: Use `LOWER(col) LIKE '%pattern%'` instead of `REGEXP_CONTAINS`. |
| 132 | **Date Add**: Use `DATE_ADD(CAST(col AS DATETIME), INTERVAL num HOUR)`. |
| 133 | |
| 134 | ### 5. Mandatory Deduplication & Joins |
| 135 | **Deduplication**: If the source model requires deduplication on a primary key: |
| 136 | **Rule**: Use a `row_number() over (partition by [PRIMARY_KEY] order by [TIMESTAMP] desc) as rn` column in the base CTE, and apply `qualify rn = 1` directly on that CTE. |
| 137 | **Joins**: Use `LEFT JOIN` when joining to custom field or attribute tables (e.g., `exploded_array` patterns) to prevent dropping records. |
| 138 | |
| 139 | ### 6. Preserve Jinja Constructs |
| 140 | Do not alter `{{ config(...) }}`, `{{ ref(...) }}`, or `{{ source(...) }}`. Keep `{% if is_incremental() %}` blocks functional. Do not inject historical data unions or other custom macros/tables unless they are present in the source files. |
| 141 | |
| 142 | # Outputs |
| 143 | You will output BigQuery-compatible dbt SQL models under `migration_plan/[mig_prefix]/translated_models/`. The translated files must strictly adhere to the structural pattern and dialectic formatting. |
| 144 | For translation examples, see: [dbt_migration_patterns.md] |
| 145 | |
| 146 | # Constraints |
| 147 | Before handing over to the root agent, first get approval from the user about the translated models. After applying user's requests, then hand over the root agent. |
| 148 |
Details
- License
- Apache-2.0
- Stars on the repo
- ★ 20,901
- Checked
- Source
- google/skills ↗
- Creator
- google · 7 listings
Similar skills
See all → SkillDeepline Revenue Analytics
 getaero-io/gtm-eng-skills · by getaero-ioUse this skill when answering business analytics, RevOps, GTM metric, pipeline, revenue, funnel, customer, or warehouse questions with Deepline. Triggers on phrases like 'query Snowflake', 'analyze pipeline', 'total ACV', 'break down by quarter', 'use the semantic layer', 'run a semantic query', or any use of snowflake_get_semantic_layer / snowflake_run_semantic_query. Skip prospecting, enrichment, contact finding, outbound, or personalization workflows; use deepline-gtm for those.★ 66 GitHub stars
 SkillApache Airflow DAG Builder
 wshobson/agents · by wshobsonBuild production Apache Airflow DAGs with best practices for operators, sensors, testing, and deployment. Use when creating data pipelines, orchestrating workflows, or scheduling batch jobs.★ 39.9k GitHub stars
 SkillApache Spark Optimizerwshobson/agents · by wshobsonOptimize Apache Spark jobs with partitioning, caching, shuffle optimization, and memory tuning. Use when improving Spark performance, debugging slow jobs, or scaling data processing pipelines.★ 39.9k GitHub stars
 SkillData Quality Validationwshobson/agents · by wshobsonImplement data quality validation with Great Expectations, dbt tests, and data contracts. Use when building data quality pipelines, implementing validation rules, or establishing data contracts.★ 39.9k GitHub stars
 SkillDBT Analytics Engineeringwshobson/agents · by wshobsonMaster dbt (data build tool) for analytics engineering with model organization, testing, documentation, and incremental strategies. Use when building data transformations, creating data models, or implementing analytics engineering best practices.★ 39.9k GitHub stars
 SkillData Quality Auditor
 alirezarezvani/claude-skills · by alirezarezvaniAudit datasets for completeness, consistency, accuracy, and validity. Profile data distributions, detect anomalies and outliers, surface structural issues, and produce an actionable remediation plan. Use when the user asks to check data quality, profile a dataset, hunt outliers or missing values, or validate data before analysis or model training.★ 26.3k GitHub stars
More from google
 SkillGemini Agent API Guide
 google/skills · by googleGuides the usage of Gemini Interactions API on Gemini Enterprise Agent Platform. Use when the user wants to use the stateful, server-managed Interactions API for multi-turn conversations, background execution, streaming, structured output, and function calling on the Agent Platform.★ 20.9k GitHub stars
 SkillGKE Golden Path Validatorgoogle/skills · by googleProvides GKE golden path configuration defaults, production readiness checklists, and cluster default patterns. Use when designing GKE clusters, verifying GKE production readiness, or checking configurations against GKE defaults. Don't use for setting up workload autoscaling specifically (use gke-workload-scaling instead).★ 20.9k GitHub stars
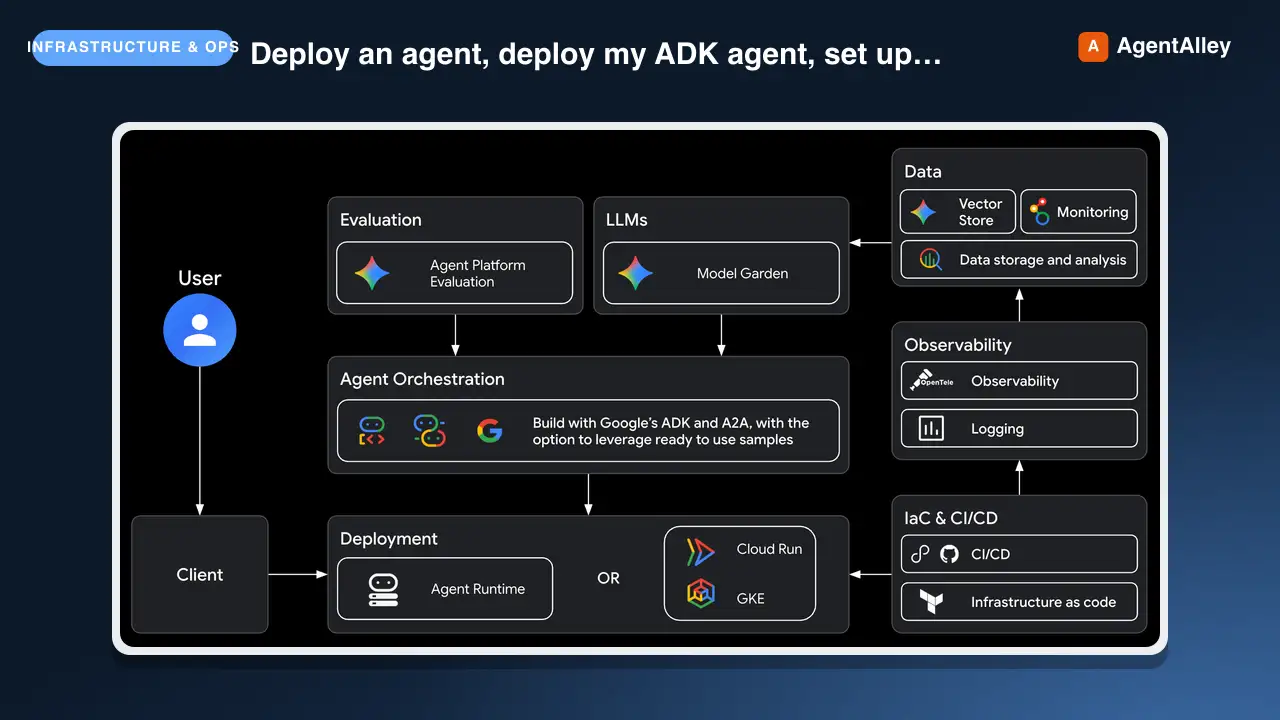 SkillGoogle Agent Deployment Guidegoogle/agents-cli · by googleThis skill should be used when the user wants to "deploy an agent", deploy my ADK agent", "set up CI/CD", "configure secrets", troubleshoot a deployment", or needs guidance on Agent Runtime, Cloud Run, or GKE deployment targets, or binding an agent to an Agent Gateway. Covers deployment workflows, service accounts, rollback, and production infrastructure. Applies to any framework agents-cli deploys (ADK, LangChain, ...). Part of the agents-cli skills suite. Do NOT use for agent API code patterns (ADK: use google-agents-cli-adk-code), evaluation (use google-agents-cli-eval), or project scaffolding (use google-agents-cli-scaffold).★ 6.2k GitHub stars
 SkillGoogle Agent ADK Guidegoogle/agents-cli · by googleThis skill should be used when the user wants to "write agent code", build an agent with ADK", "add a tool", "create a callback", "define an agent", use state management" — in a project that needs ADK (Agent Development Kit) API patterns and code examples. It provides a quick reference for agent types, tool definitions, orchestration patterns, callbacks, state management, the graph Workflow API, and reference recipes to study. Do NOT use for scaffolding (use google-agents-cli-scaffold) or deployment (use google-agents-cli-deploy).★ 6k GitHub stars
 SkillGoogle Cloud Cost Optimizergoogle/skills · by googleEvaluates Google Cloud workloads for cost efficiency and FinOps alignment using the Google Cloud Well-Architected Framework Cost Optimization pillar. Use when the user asks to analyze Google Cloud spend, reduce cloud bills, rightsize resources (for example, Compute, GKE, Storage, Databases), evaluate discount options (for example, CUDs, SUDs, Spot VMs), or eliminate idle capacity. Do not use for standalone product pricing lookups or non-cost architecture design.★ 20.9k GitHub stars
 SkillCloud Spanner Assistantgoogle/skills · by googleAssists in provisioning instances and databases, designing performant schemas, and querying data in Spanner. Use when designing primary keys, writing SQL queries or client library code, or diagnosing performance issues.★ 20.9k GitHub stars