Cloud Spanner Assistant
Spanner basics
Assists in provisioning instances and databases, designing performant schemas, and querying data in Spanner. Use when designing primary keys, writing SQL queries or client library code, or diagnosing performance issues.
---
name: spanner-basics
metadata:
  version: "1.1.0"
  category: Databases
description: >-
  Assists in provisioning instances and databases, designing performant schemas, and querying data in Spanner. Use when designing primary keys, writing SQL queries or client library code, or diagnosing performance issues.
---

# Spanner Basics

This skill provides core workflows and guidance for administering and developing with Google Cloud Spanner, a fully managed, mission-critical database service offering global transactional consistency and automatic, synchronous replication for high availability.

## Core Principles

-   **Performance First:** Spanner scales horizontally. Efficiency is tied to
    Primary Key design. Always warn against using monotonically increasing/decreasing
    values (like sequential timestamps) as the first part of a primary key to avoid hotspots.
Overview
This skill provides core workflows and guidance for administering and developing with Google Cloud Spanner, a fully managed, mission-critical database service offering global transactional consistency and automatic, synchronous replication for high availability.
Manual install (npx, ZIP)
npx skills add google/skills --skill spanner-basics -g -a claude-codenpx degit google/skills/skills/cloud/spanner-basics#main ~/.claude/skills/spanner-basicsConnects with Agent Alley MCP · agentalley.io/mcp
Files included
SKILL.md3.3 KB
Read SKILL.md here
Show the full text53 lines
Spanner Basics
This skill provides core workflows and guidance for administering and developing with Google Cloud Spanner, a fully managed, mission-critical database service offering global transactional consistency and automatic, synchronous replication for high availability.
Core Principles
- Performance First: Spanner scales horizontally. Efficiency is tied to Primary Key design. Always warn against using monotonically increasing/decreasing values (like sequential timestamps) as the first part of a primary key to avoid hotspots.
- Schema Design: Prefer interleaved tables for strongly related parent-child data that is frequently accessed together.
Safety
[!CAUTION] CRITICAL INSTRUCTION: You MUST obtain explicit user confirmation before making any non-emulator database changes (DML or DDL) or destructive operations (such as dropping tables, indexes, or any other Spanner resources). Do not execute them automatically; instead, output the command (e.g.,
gcloud spanner databases ddl update) and ask for explicit user approval. When database access is unavailable or authentication fails, do not block on trying to verify the existence of the instance, database, or table. Assume the provided resources exist and directly generate the DDL commands.
Common Workflows
Schema Evolution & DDL
- Use
gcloud spanner databases ddl updateto apply schema updates (such as CREATE, ALTER, or DROP tables and indexes). - Reference schema-design.md for guidelines on primary key selection and interleaved tables.
Diagnosing Performance Issues
- Use
SPANNER_SYStables to identify slow or resource-intensive queries. - For example, query
SPANNER_SYS.QUERY_STATS_TOP_HOURto find queries with the highest CPU usage.
Reference Directory
- Core Concepts: Explanation of Spanner internals, architecture, and design.
- CLI Usage: Essential
gcloud spannercommand-line operations for managing instances and databases. - IAM Security: Roles, permissions, and data governance best practices for Spanner.
- Client Library Usage: Using Google Cloud client libraries for Spanner (Java, Go, Python, Node.js).
- Terraform Usage: Infrastructure as Code examples for provisioning Spanner instances and databases.
- MCP Usage: Using the Spanner remote MCP server.
- PostgreSQL Dialect: Best practices and examples for using the PostgreSQL interface in Spanner.
- Queues Usage: Cloud Spanner Queues: mental model, design constraints, and links related to transactional message queues.
- Schema Design: Guidelines on primary key selection and interleaved tables for performance.
If you need product information that's not found in these references, use the
search_documents tool of the Developer Knowledge MCP server.
| 1 | |
| 2 | name spanner-basics |
| 3 | metadata |
| 4 | version "1.1.0" |
| 5 | category Databases |
| 6 | description >- |
| 7 | Assists in provisioning instances and databases, designing performant schemas, and querying data in Spanner. Use when designing primary keys, writing SQL queries or client library code, or diagnosing performance issues. |
| 8 | |
| 9 | |
| 10 | # Spanner Basics |
| 11 | |
| 12 | This skill provides core workflows and guidance for administering and developing with Google Cloud Spanner, a fully managed, mission-critical database service offering global transactional consistency and automatic, synchronous replication for high availability. |
| 13 | |
| 14 | ## Core Principles |
| 15 | |
| 16 | **Performance First:** Spanner scales horizontally. Efficiency is tied to |
| 17 | Primary Key design. Always warn against using monotonically increasing/decreasing |
| 18 | values (like sequential timestamps) as the first part of a primary key to avoid hotspots. |
| 19 | **Schema Design:** Prefer interleaved tables for strongly related parent-child data |
| 20 | that is frequently accessed together. |
| 21 | |
| 22 | ## Safety |
| 23 | |
| 24 | > [!CAUTION] **CRITICAL INSTRUCTION:** You MUST obtain explicit user confirmation before making any non-emulator database changes (DML or DDL) or destructive operations (such as dropping tables, indexes, or any other Spanner resources). Do not execute them automatically; instead, output the command (e.g., `gcloud spanner databases ddl update`) and ask for explicit user approval. |
| 25 | > When database access is unavailable or authentication fails, do not block on trying to verify the existence of the instance, database, or table. Assume the provided resources exist and directly generate the DDL commands. |
| 26 | |
| 27 | ## Common Workflows |
| 28 | |
| 29 | ### Schema Evolution & DDL |
| 30 | |
| 31 | Use `gcloud spanner databases ddl update` to apply schema updates (such as CREATE, ALTER, or DROP tables and indexes). |
| 32 | Reference [schema-design.md] for guidelines on primary key selection and interleaved tables. |
| 33 | |
| 34 | ### Diagnosing Performance Issues |
| 35 | |
| 36 | Use `SPANNER_SYS` tables to identify slow or resource-intensive queries. |
| 37 | For example, query `SPANNER_SYS.QUERY_STATS_TOP_HOUR` to find queries with the highest CPU usage. |
| 38 | |
| 39 | ## Reference Directory |
| 40 | |
| 41 | [Core Concepts]: Explanation of Spanner internals, architecture, and design. |
| 42 | [CLI Usage]: Essential `gcloud spanner` command-line operations for managing instances and databases. |
| 43 | [IAM Security]: Roles, permissions, and data governance best practices for Spanner. |
| 44 | [Client Library Usage]: Using Google Cloud client libraries for Spanner (Java, Go, Python, Node.js). |
| 45 | [Terraform Usage]: Infrastructure as Code examples for provisioning Spanner instances and databases. |
| 46 | [MCP Usage]: Using the Spanner remote MCP server. |
| 47 | [PostgreSQL Dialect]: Best practices and examples for using the PostgreSQL interface in Spanner. |
| 48 | [Queues Usage]: Cloud Spanner Queues: mental model, design constraints, and links related to transactional message queues. |
| 49 | [Schema Design]: Guidelines on primary key selection and interleaved tables for performance. |
| 50 | |
| 51 | If you need product information that's not found in these references, use the |
| 52 | `search_documents` tool of the Developer Knowledge MCP server. |
| 53 |
Details
- License
- Apache-2.0
- Stars on the repo
- ★ 20,901
- Checked
- Source
- google/skills ↗
- Creator
- google · 7 listings
Similar skills
See all → SkillCross-Platform Reverse Engineer
 morluto/rea · by morlutoReverse engineer native, managed, Electron/JavaScript, packaged, firmware, and browser targets with REA. Use shipped-artifact or requested runtime evidence to explain features, compare versions, decompile code, or guide a reconstruction. Skip REA for ordinary source-repository architecture analysis.★ 316k GitHub stars
 SkillBrainstorm Ideas
 obra/superpowers · by obraYou MUST use this before any creative work - creating features, building components, adding functionality, or modifying behavior. Explores user intent, requirements and design before implementation.★ 290k GitHub stars
 SkillCode Review Feedback Analyzerobra/superpowers · by obraUse when receiving code review feedback, before implementing suggestions, especially if feedback seems unclear or technically questionable - requires technical rigor and verification, not performative agreement or blind implementation★ 290k GitHub stars
 SkillBug Diagnosis Framework
 mattpocock/skills · by mattpocockDiagnosis loop for hard bugs and performance regressions. Use when the user says "diagnose"/"debug this", or reports something broken/throwing/failing/slow.★ 267k GitHub stars
 SkillImplement Specmattpocock/skills · by mattpocockImplement the result of /to-spec and /to-tickets in code.★ 267k GitHub stars
 SkillPR Description Writermattpocock/skills · by mattpocockUse when writing a PR body.★ 267k GitHub stars
More from google
 SkillSnowflake to BigQuery Translator
 google/skills · by googleTranslates Snowflake dbt SQL models to Standardized BigQuery SQL. Handles SQL compilation, Jinja macro placeholder masking, BigQuery Translation Service migration workflows, AST-based config transformations, explicit type casting, JSON extraction standardization, and deduplication. Use when migrating Snowflake dbt pipelines or models to Google Cloud BigQuery. Don't use for generic BigQuery queries or non-Snowflake SQL migrations.★ 20.9k GitHub stars
 SkillGemini Agent API Guidegoogle/skills · by googleGuides the usage of Gemini Interactions API on Gemini Enterprise Agent Platform. Use when the user wants to use the stateful, server-managed Interactions API for multi-turn conversations, background execution, streaming, structured output, and function calling on the Agent Platform.★ 20.9k GitHub stars
 SkillGKE Golden Path Validatorgoogle/skills · by googleProvides GKE golden path configuration defaults, production readiness checklists, and cluster default patterns. Use when designing GKE clusters, verifying GKE production readiness, or checking configurations against GKE defaults. Don't use for setting up workload autoscaling specifically (use gke-workload-scaling instead).★ 20.9k GitHub stars
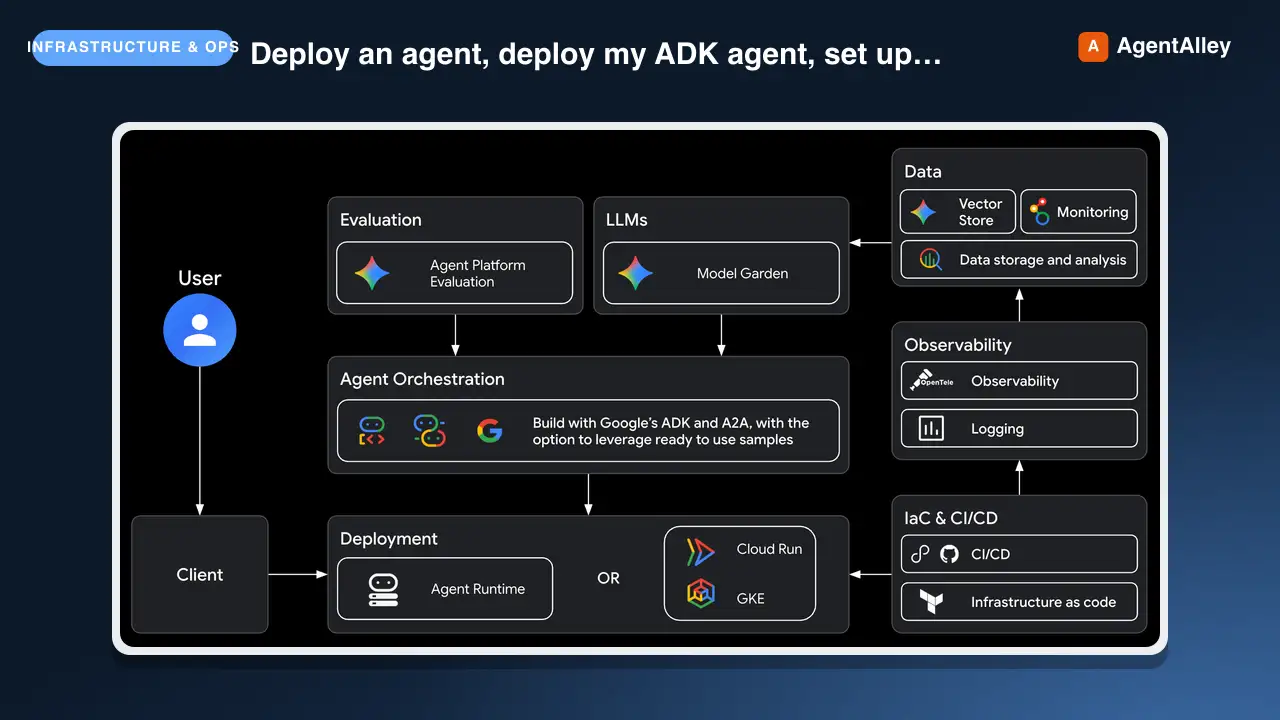 SkillGoogle Agent Deployment Guidegoogle/agents-cli · by googleThis skill should be used when the user wants to "deploy an agent", deploy my ADK agent", "set up CI/CD", "configure secrets", troubleshoot a deployment", or needs guidance on Agent Runtime, Cloud Run, or GKE deployment targets, or binding an agent to an Agent Gateway. Covers deployment workflows, service accounts, rollback, and production infrastructure. Applies to any framework agents-cli deploys (ADK, LangChain, ...). Part of the agents-cli skills suite. Do NOT use for agent API code patterns (ADK: use google-agents-cli-adk-code), evaluation (use google-agents-cli-eval), or project scaffolding (use google-agents-cli-scaffold).★ 6.2k GitHub stars
 SkillGoogle Agent ADK Guidegoogle/agents-cli · by googleThis skill should be used when the user wants to "write agent code", build an agent with ADK", "add a tool", "create a callback", "define an agent", use state management" — in a project that needs ADK (Agent Development Kit) API patterns and code examples. It provides a quick reference for agent types, tool definitions, orchestration patterns, callbacks, state management, the graph Workflow API, and reference recipes to study. Do NOT use for scaffolding (use google-agents-cli-scaffold) or deployment (use google-agents-cli-deploy).★ 6k GitHub stars
 SkillGoogle Cloud Cost Optimizergoogle/skills · by googleEvaluates Google Cloud workloads for cost efficiency and FinOps alignment using the Google Cloud Well-Architected Framework Cost Optimization pillar. Use when the user asks to analyze Google Cloud spend, reduce cloud bills, rightsize resources (for example, Compute, GKE, Storage, Databases), evaluate discount options (for example, CUDs, SUDs, Spot VMs), or eliminate idle capacity. Do not use for standalone product pricing lookups or non-cost architecture design.★ 20.9k GitHub stars